
Headroom
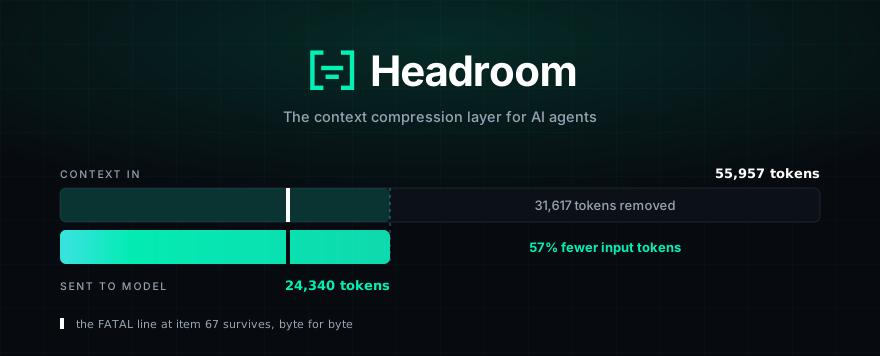
If you're burning thousands of tokens on tool outputs, logs, or RAG results before they even reach the LLM, this MCP server gives you compress and retrieve operations that claim 60 to 95 percent savings while preserving answer quality. It routes JSON through SmartCrusher, code through an AST compressor, and prose through a Kompress model, then caches originals locally so the LLM can pull them back with headroom_retrieve if needed. The same library also ships as a proxy and agent wrapper for Claude, Cursor, and Aider. Benchmarks on GSM8K and TruthfulQA show no accuracy drop. You'd reach for this when context windows fill up faster than your budget allows or when you want the same agent behavior at a fraction of the API cost.
- GitHub stars
- 23.9K
- tools
- 3
- transport
- STDIO
Tools
3 toolsPublic tool metadata for what this MCP can expose to an agent.
headroom_compressCompresses context for an MCP client.
Compresses context for an MCP client.
No parameter schema in public metadata yet.
headroom_retrieveRetrieves original content that was compressed.
Retrieves original content that was compressed.
No parameter schema in public metadata yet.
headroom_statsReports compression statistics.
Reports compression statistics.
No parameter schema in public metadata yet.
Sponsors
 Agent CaffeineSponsoredClose your lid, come back to finished work
 SnugSponsoredThe clipboard manager for the AI eraPromote your product hereReach 125k+ visitors monthly
 WaxSponsoredBlock anything with supervision, without erasing your iPhonePromote your product hereReach 125k+ visitors monthly
 knobsSponsoredSee your site on any phone, any day, in any language
Readme
Details
- Repository
- github.com/chopratejas/headroom
- Category
- AI & LLM Tools
- Package
headroom- Transport
- STDIO
Related AI & LLM Tools MCP servers
View all PALbeehiveinnovations/pal-mcp-serverThe power of Claude Code / GeminiCLI / CodexCLI + [Gemini / OpenAI / OpenRouter / Azure / Grok / Ollama / Custom Model / All Of The Above] working as one.11.5Kstars
 Talk to Figmagrab/cursor-talk-to-figma-mcpTalkToFigma: MCP integration between AI Agent (Cursor, Claude Code) and Figma, allowing Agentic AI to communicate with Figma for reading designs and modifying t6.8Kstars
 PaperBananallmsresearch/paperbananaGenerate academic diagrams and statistical plots from text using multi-agent AI.2Kstars
 Projectmemriponcm/projectmemCoding agent memory — one local MCP server for every project. Warns before repeating failed fixes.877stars
 Codemanark0n/codemanStart, prompt and read AI coding agent sessions (Claude Code, Codex, Gemini CLI and more) in Codeman838stars
 Context Portalgreatscottymac/context-portalContext Portal (ConPort): A memory bank MCP server building a project-specific knowledge graph to supercharge AI assistants. Enables powerful Retrieval Augmente762stars