Macos Vision Mcp
Wraps Apple's Vision Framework to run OCR, face detection, barcode reading, and image classification entirely on your Mac. Instead of sending a 44-page PDF to Claude as 73,500 tokens, it extracts structured text locally first (paragraphs, bounding boxes, reading order) and costs around 2,400 tokens. Works with any MCP client over stdio. Exposes five tools: ocr_image for text extraction, detect_faces, detect_barcodes, classify_image, and analyze_document for full pipelines that return JSON ready for the model to rebuild as Markdown or HTML. Requires macOS 13.0+ and runs offline after install. Useful when you're processing contracts, invoices, or medical records and want the file to stay local while still getting structured output the LLM can reason over.
- GitHub stars
- 8
- tools
- 13
- transport
- STDIO
- last updated
- Aug 25, 2026
Tools
13 toolsPublic tool metadata for what this MCP can expose to an agent.
ocr_imageExtract text from an image or PDF (JPG, PNG, HEIC, TIFF, PDF). Returns plain text, or per-page paragraphs + text blocks with lineId / paragraphId and bounding boxes. Accepts start_page / max_pages for partial PDF OCR.
Extract text from an image or PDF (JPG, PNG, HEIC, TIFF, PDF). Returns plain text, or per-page paragraphs + text blocks with lineId / paragraphId and bounding boxes. Accepts start_page / max_pages for partial PDF OCR.
No parameter schema in public metadata yet.
detect_facesDetect human faces and return their count and positions.
Detect human faces and return their count and positions.
No parameter schema in public metadata yet.
detect_barcodesRead QR codes, EAN, UPC, Code128, PDF417, Aztec, and other 1D/2D codes.
Read QR codes, EAN, UPC, Code128, PDF417, Aztec, and other 1D/2D codes.
No parameter schema in public metadata yet.
detect_documentDetect the four corner points of a document in a photo (paper, receipt, ID). Useful as a crop / deskew hint before OCR.
Detect the four corner points of a document in a photo (paper, receipt, ID). Useful as a crop / deskew hint before OCR.
No parameter schema in public metadata yet.
classify_imageClassify image content into 1000+ categories with confidence scores.
Classify image content into 1000+ categories with confidence scores.
No parameter schema in public metadata yet.
analyze_documentReturns structured JSON with reading-order paragraphs, raw text blocks (bbox / confidence), faces, barcodes, and rectangles — ready for the model to reconstruct into Markdown, HTML, or anything else. Also accepts start_page / max_pages for long PDFs.
Returns structured JSON with reading-order paragraphs, raw text blocks (bbox / confidence), faces, barcodes, and rectangles — ready for the model to reconstruct into Markdown, HTML, or anything else. Also accepts start_page / max_pages for long PDFs.
No parameter schema in public metadata yet.
capture_screenScreenshot the main display, a window (even occluded), an app's frontmost window, or a region. Returns the file path + screen-point frame — never the image bytes.
Screenshot the main display, a window (even occluded), an app's frontmost window, or a region. Returns the file path + screen-point frame — never the image bytes.
No parameter schema in public metadata yet.
list_windowsList on-screen windows with global screen-point bounds, front-to-back.
List on-screen windows with global screen-point bounds, front-to-back.
No parameter schema in public metadata yet.
read_screen_textCapture + OCR in one step — read what an app shows right now, fully offline.
Capture + OCR in one step — read what an app shows right now, fully offline.
No parameter schema in public metadata yet.
find_elementFind a UI element by visible text; returns clickPoint {x,y} in global screen points (exact → substring → fuzzy matching with near-miss reporting).
Find a UI element by visible text; returns clickPoint {x,y} in global screen points (exact → substring → fuzzy matching with near-miss reporting).
No parameter schema in public metadata yet.
assert_textLocal pass/fail assertion that text is present on / absent from the screen — the verdict is computed on your Mac, not by a cloud model.
Local pass/fail assertion that text is present on / absent from the screen — the verdict is computed on your Mac, not by a cloud model.
No parameter schema in public metadata yet.
vision_capabilitiesReport macOS version, Screen Recording / Accessibility permission state, and displays.
Report macOS version, Screen Recording / Accessibility permission state, and displays.
No parameter schema in public metadata yet.
ui_snapshotReturn the whole layout as JSON: every element's exact box, role, label and state from the accessibility tree, optionally with colours and fonts — plus visible text the tree does not account for.
Return the whole layout as JSON: every element's exact box, role, label and state from the accessibility tree, optionally with colours and fonts — plus visible text the tree does not account for.
No parameter schema in public metadata yet.
Sponsors
 Agent CaffeineSponsoredClose your lid, come back to finished work
 SnugSponsoredThe clipboard manager for the AI eraPromote your product hereReach 125k+ visitors monthly
 WaxSponsoredBlock anything with supervision, without erasing your iPhonePromote your product hereReach 125k+ visitors monthly
 knobsSponsoredSee your site on any phone, any day, in any language
Readme
macos-vision-mcp
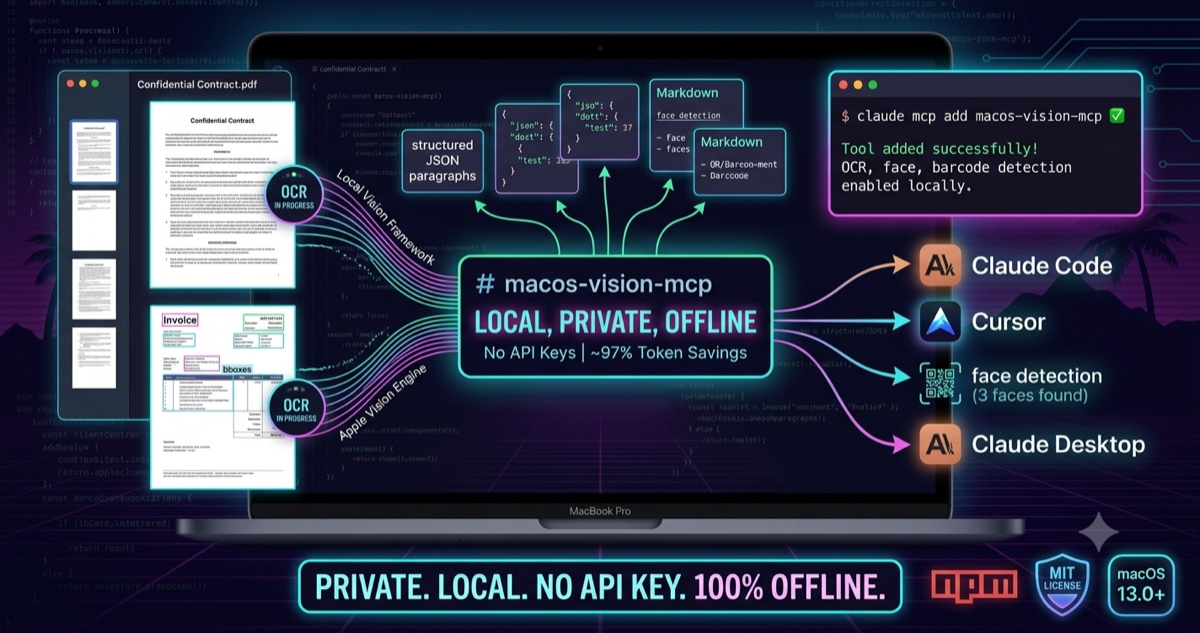
Your documents and your screen stay on the machine. Only extracted text and structured JSON ever reach the model.
Local, private, offline OCR and UI testing for any MCP client — no API keys, no uploads. Cut document token costs by ~97%, and let an agent see and click your Mac's UI without a single screenshot leaving the machine.
Details
- Repository
- github.com/woladi/macos-vision-mcp
- Package
macos-vision-mcp- Transport
- STDIO
- Registry
- MCP registry, active